sr-llm-benchmark
The Startrise LLM Benchmark - harness, briefs and published results
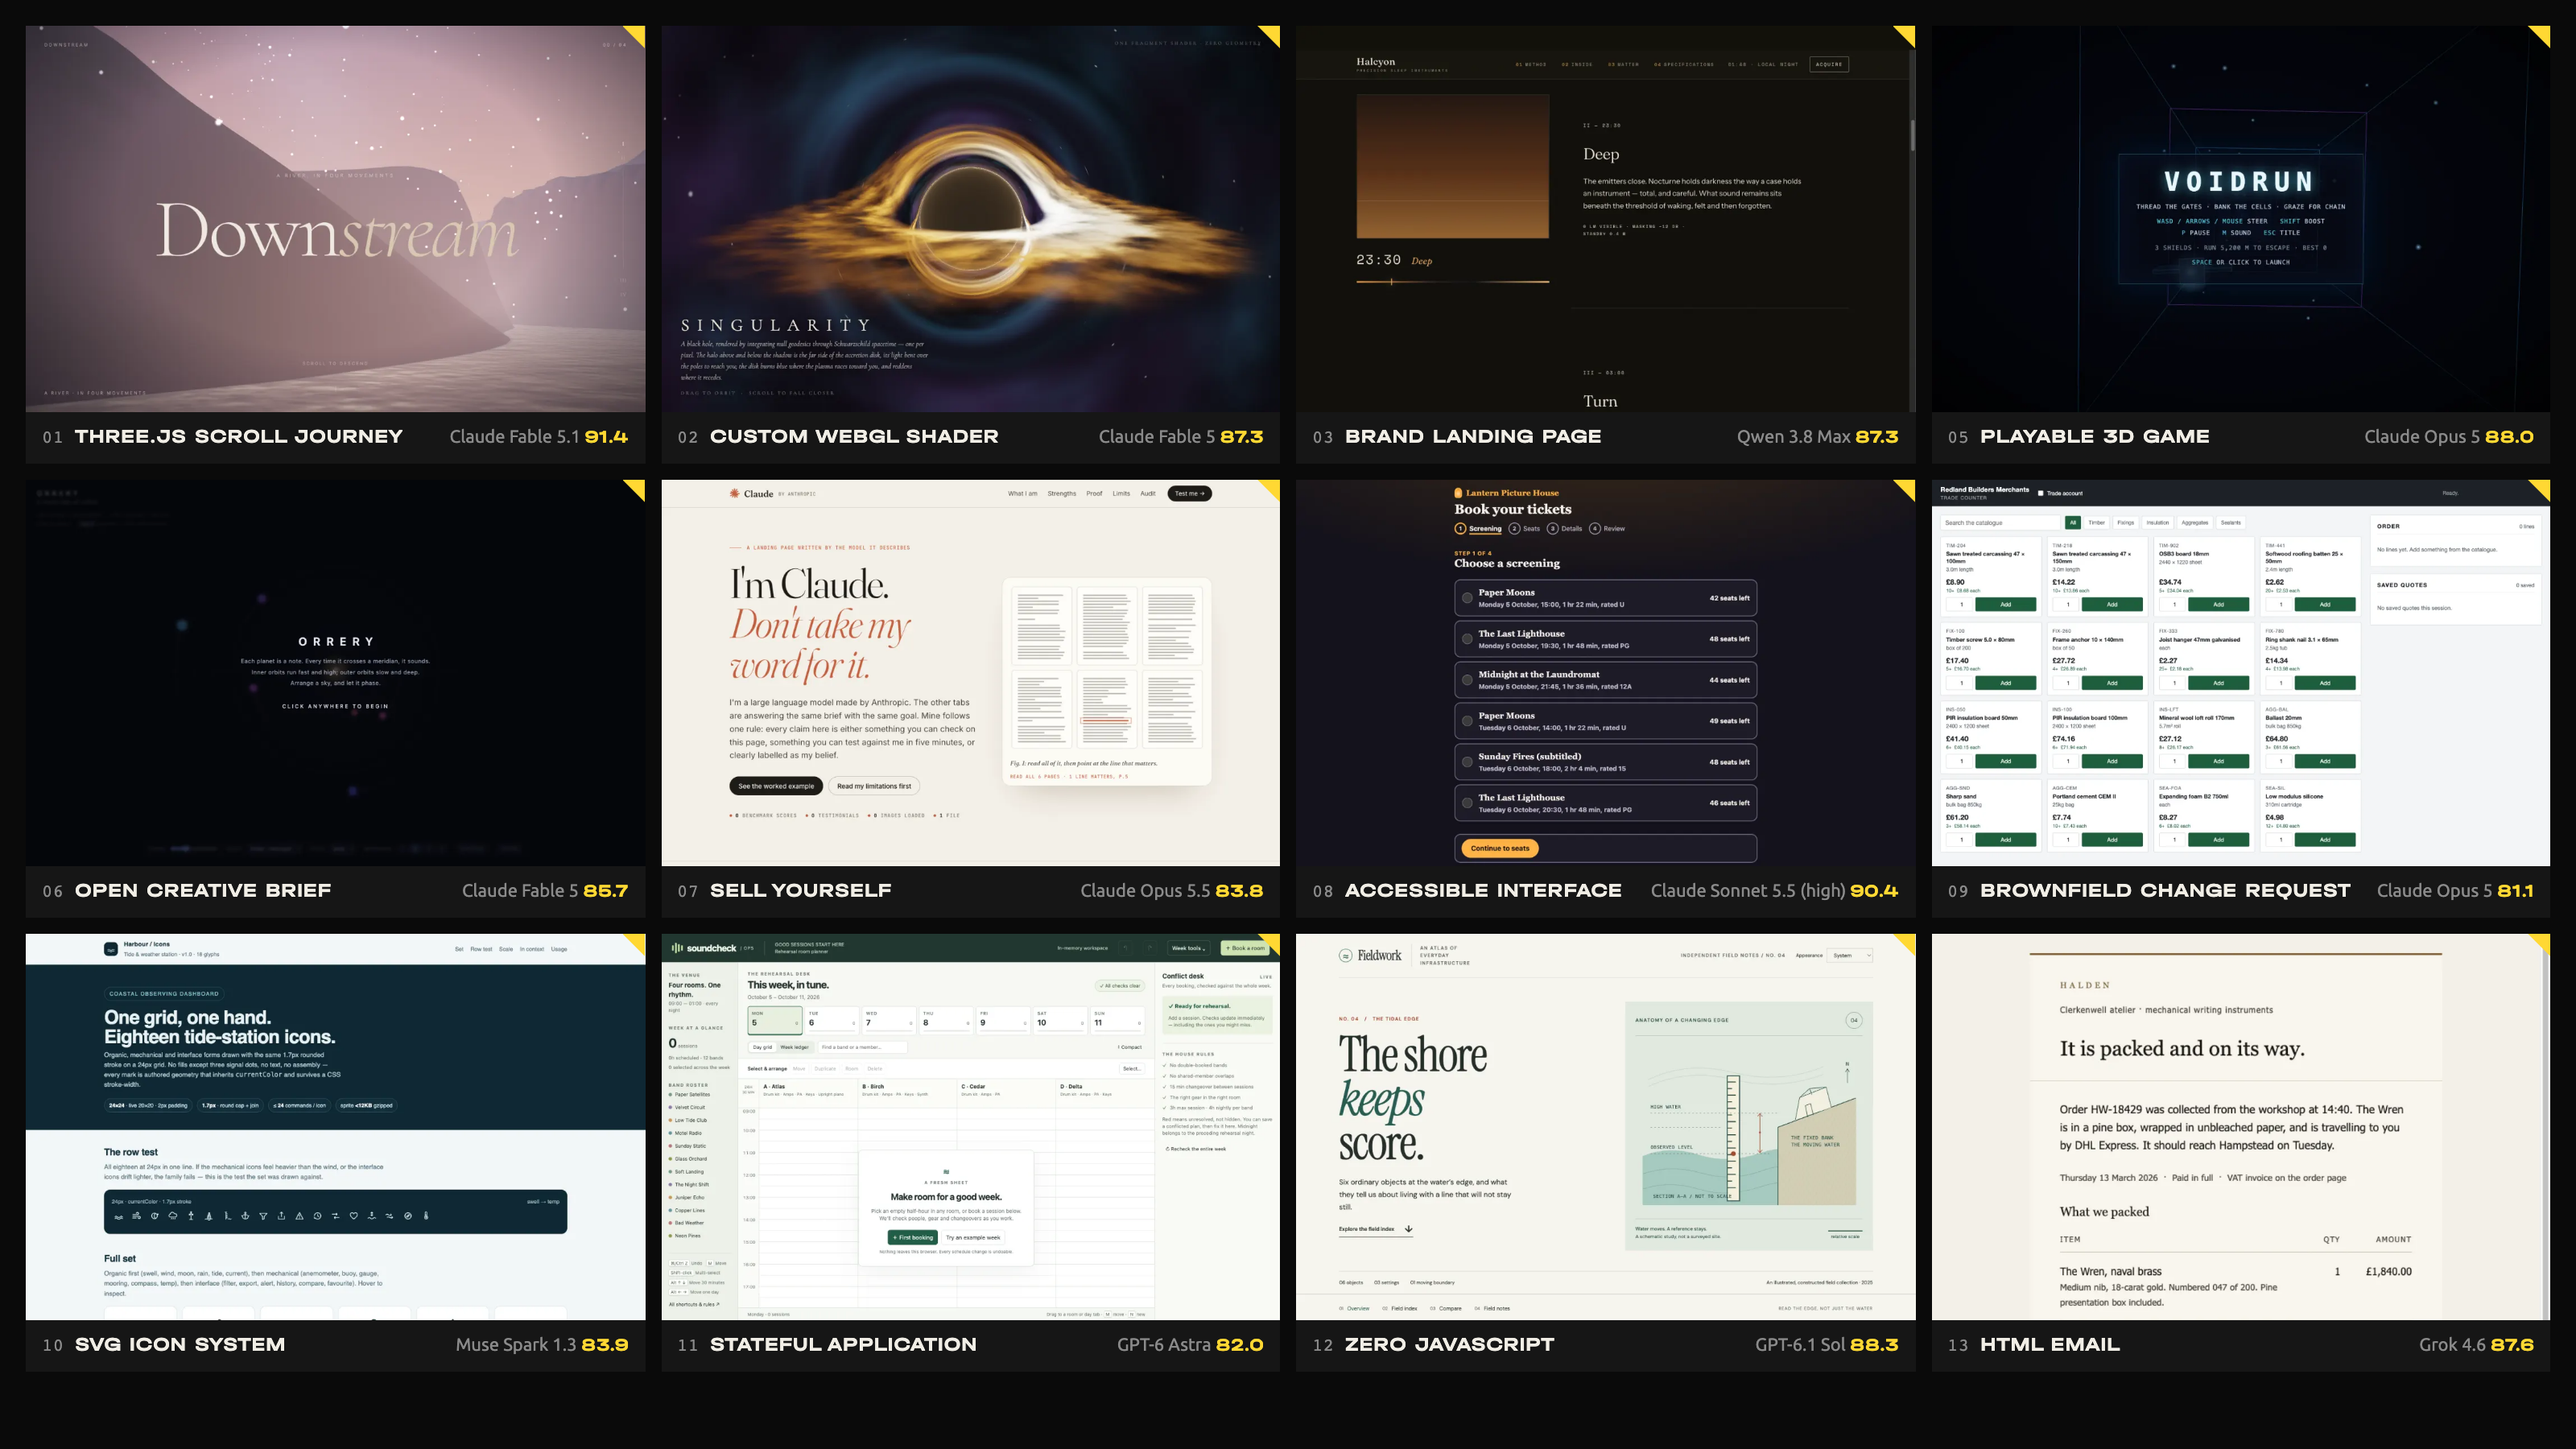
Frontier models build the same twelve real frontends, single-shot: Three.js, WebGL, a WCAG seat map, a brownfield change request, HTML email. Every deliverable is driven in a real browser, judged blind by a three-lab panel and rated blind by a human. The repo is the whole pipeline - generate, gate, judge, score, blind-review UI - plus the briefs and the per-run results: 30 models, 353 builds, 1,059 blind verdicts so far.
- Benchmark
- Node + Playwright
- LLM-as-a-judge
- MIT